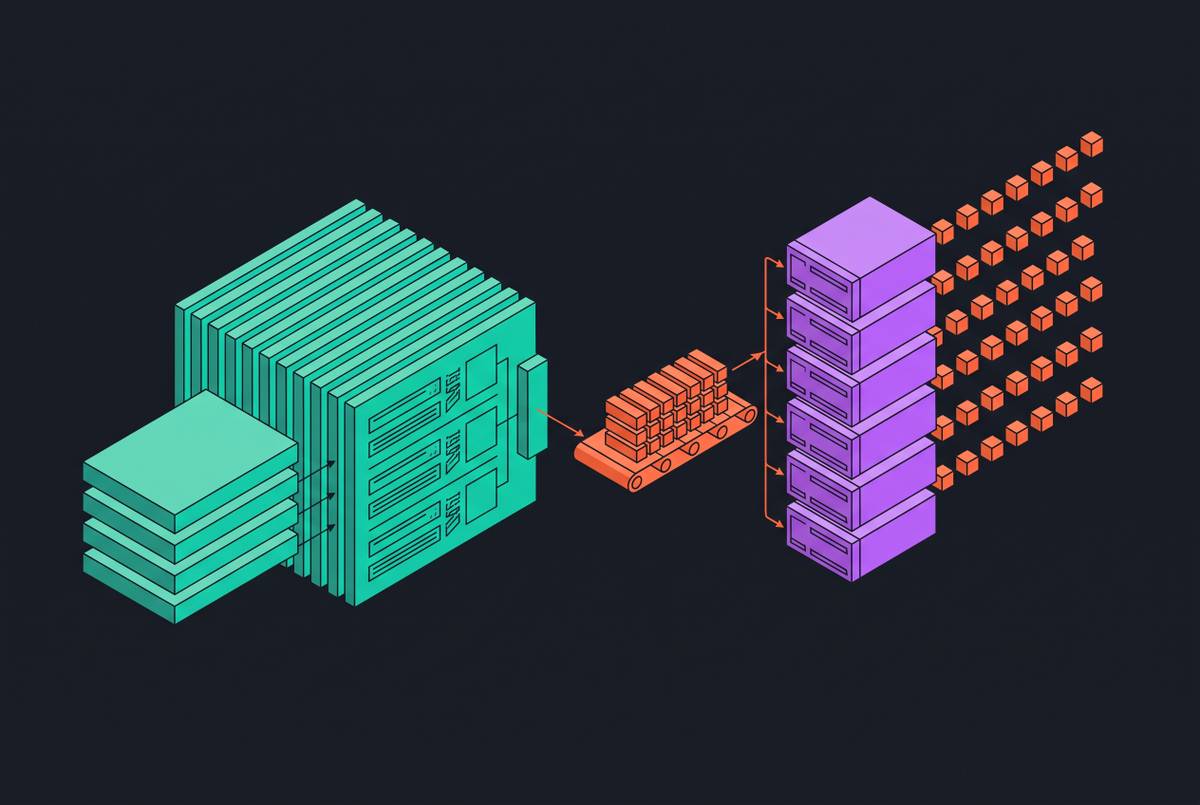
Prefill and Decode Disaggregation in LLM Serving
Splitting prefill and decode onto separate GPUs unlocks independent scaling for LLM serving.
Rohan Reyes
Contributing Editor
Rohan Reyes is a contributing editor at Inference Engineering covering features. Based in Seoul, Rohan has written for Inference Engineering since 2016.
1 story · Seoul
Splitting prefill and decode onto separate GPUs unlocks independent scaling for LLM serving.