Controlling KV Cache Memory Growth Without Sacrificing Throughput
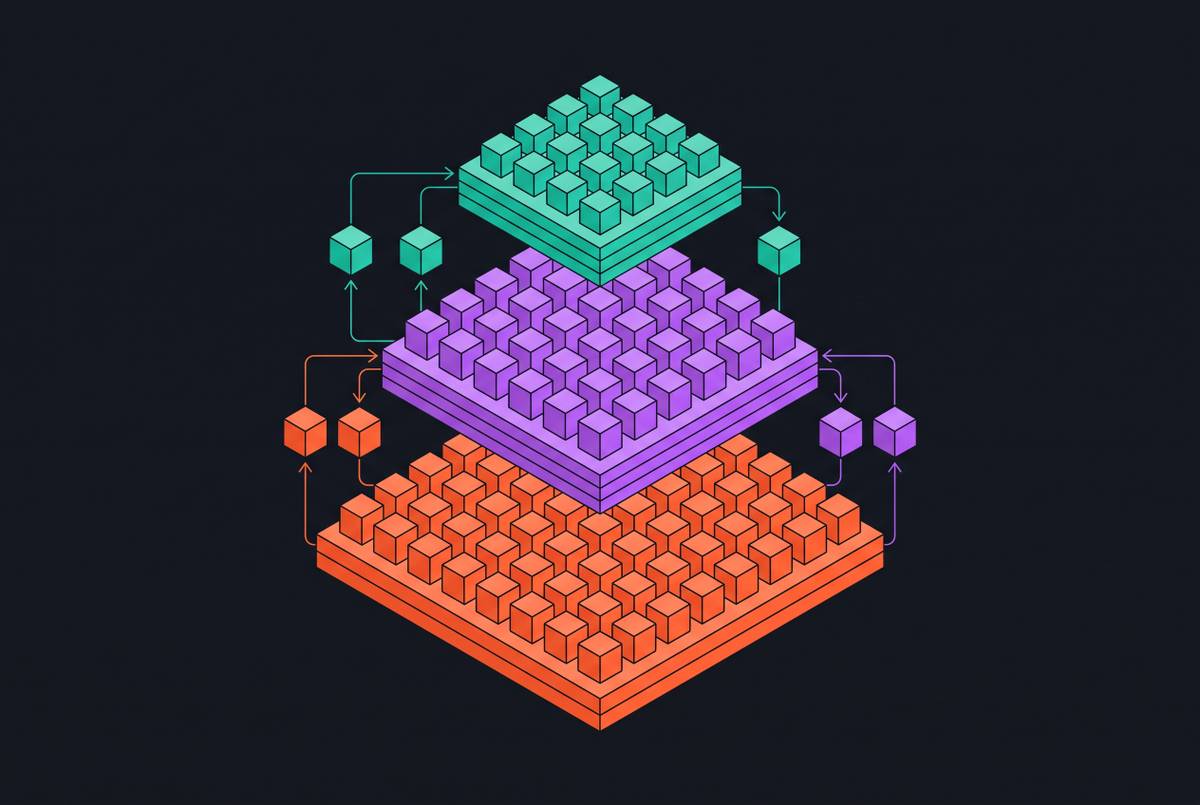
A four-layer framework combines paging, quantization, eviction.
Priya Subramaniam
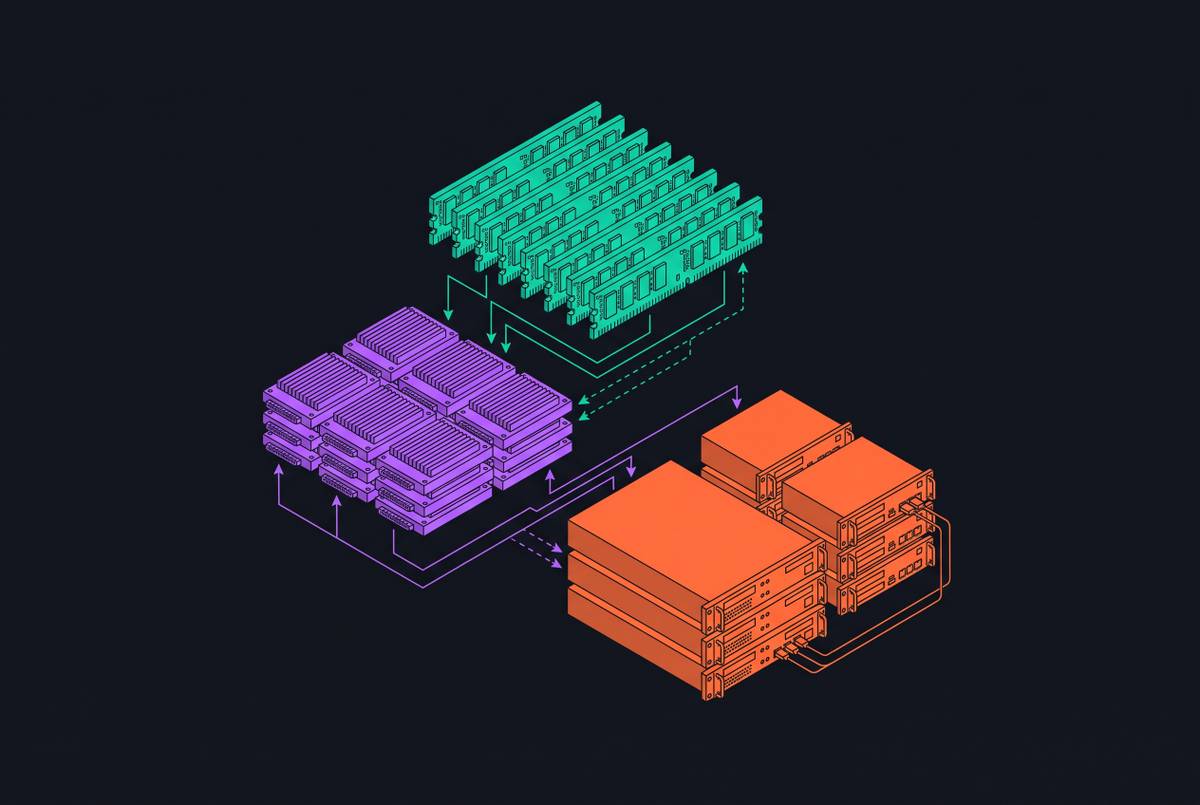
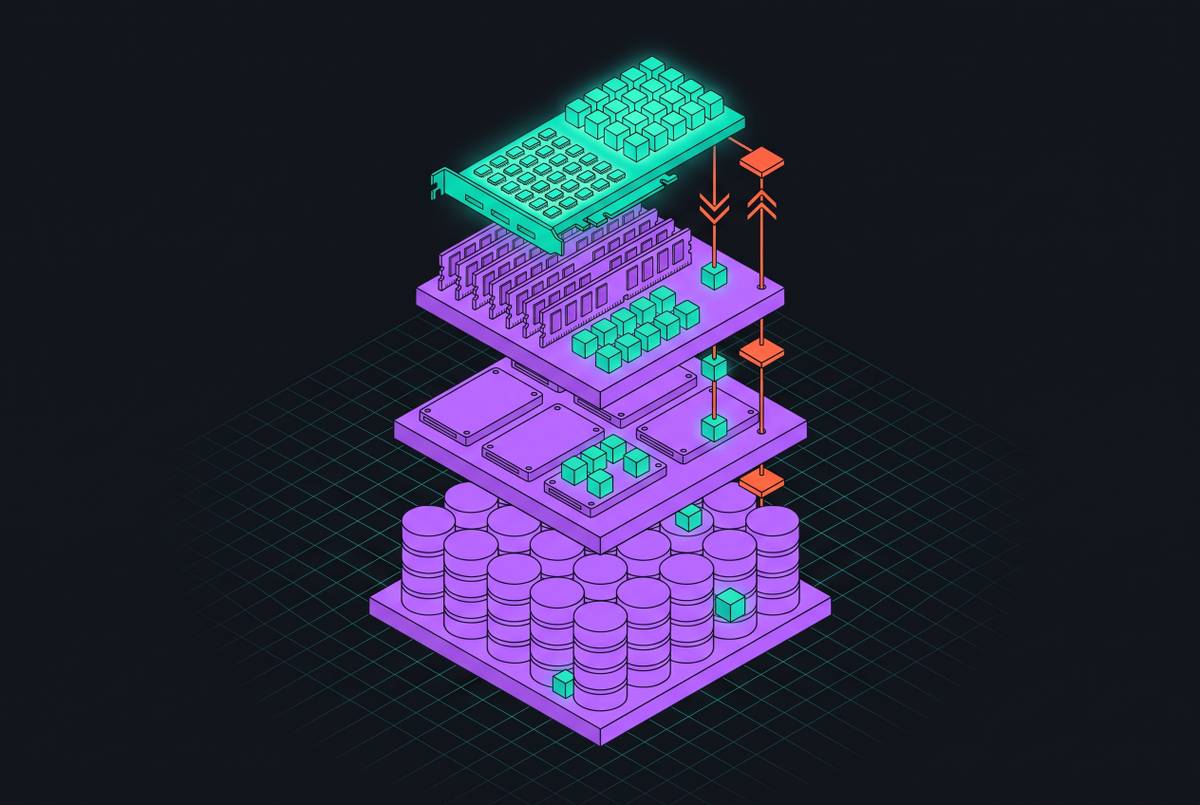
How to move LLM cache between GPU, DRAM, and storage.
A four-layer framework combines paging, quantization, eviction.
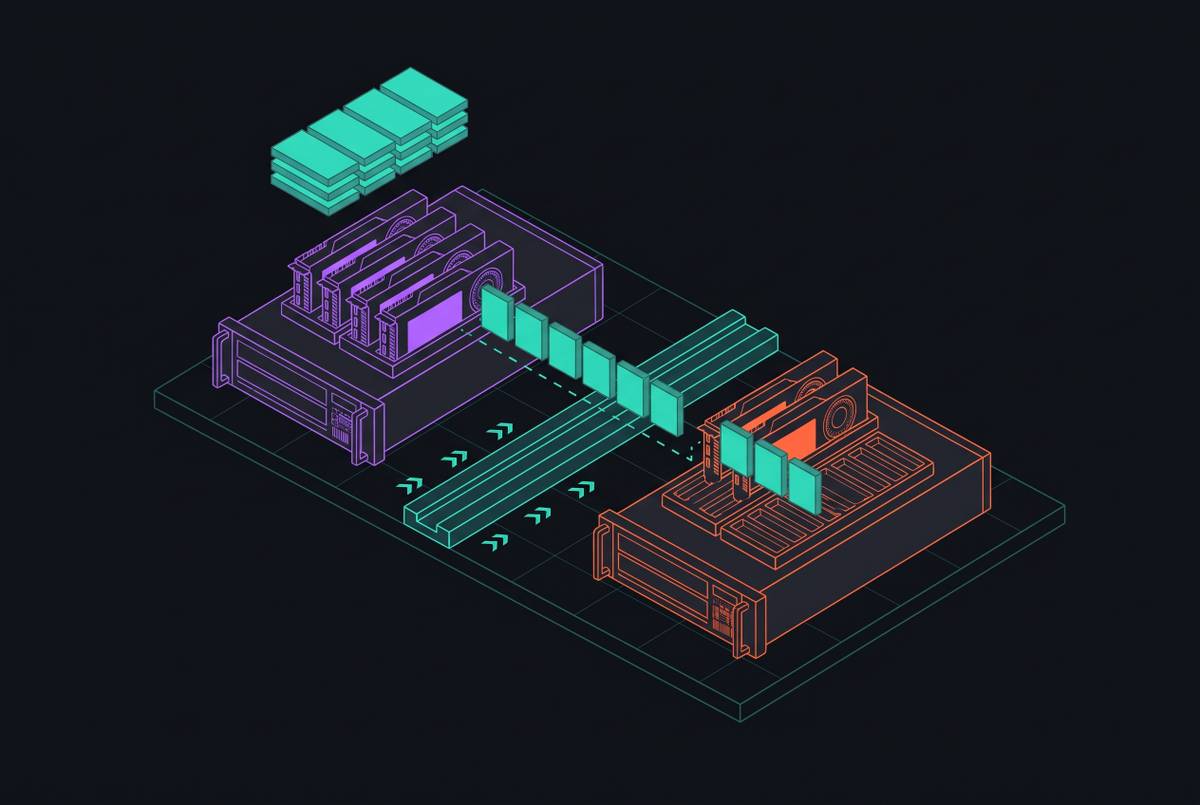
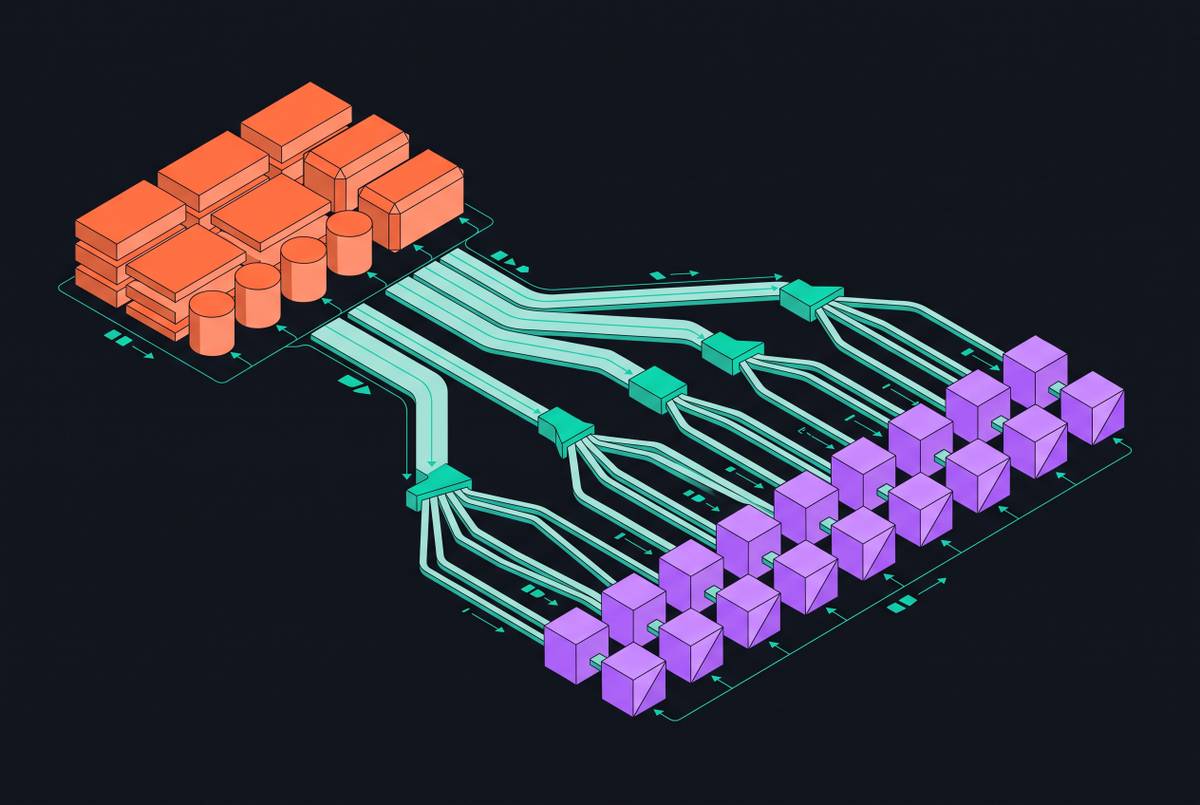
Push mode RDMA writes and pull mode reads create a 98x throughput gap on identical hardware.
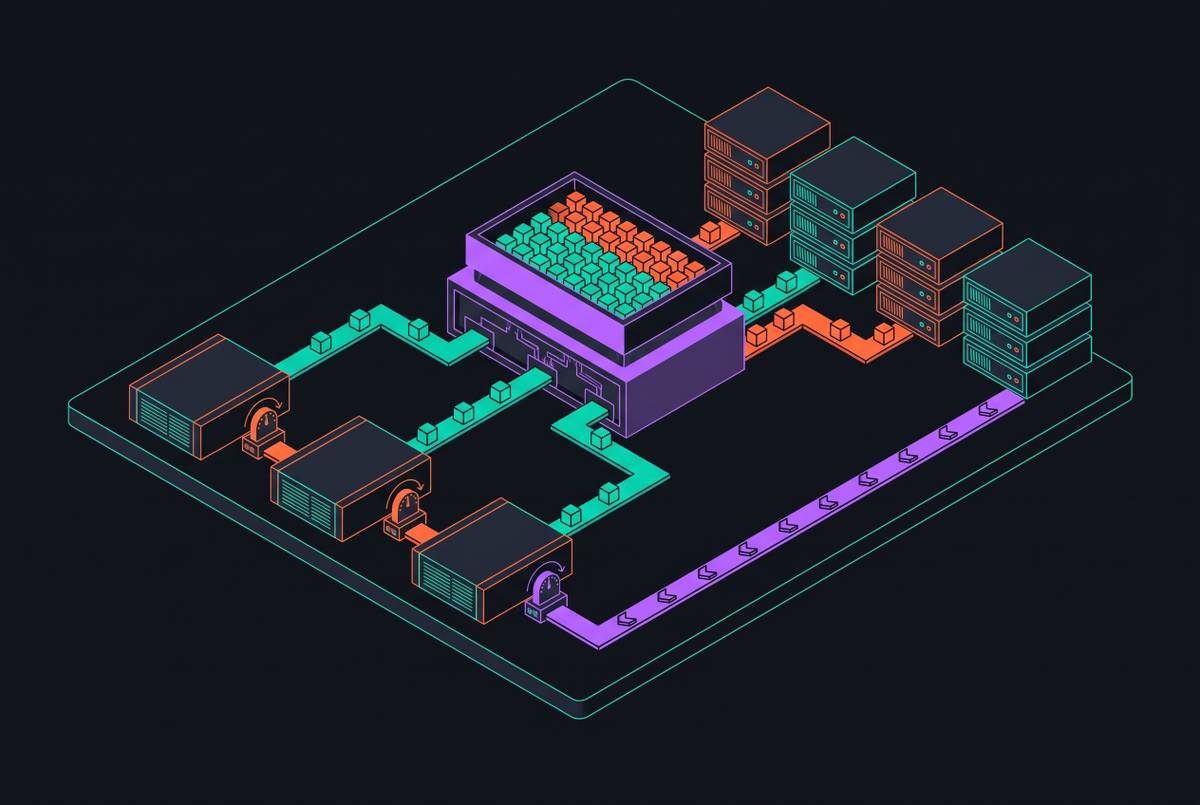
Configuring ECN, DCQCN, and PFC settings correctly is essential for preventing fabric bottlenecks.
Managing KV cache as a shared resource across request lifecycles improves LLM serving efficiency.