KV Cache Tiering and Eviction Policy Design for 128k Context Windows
Smart eviction policies balance reconstruction cost and future access patterns at scale.
Serving large models at long context at scale requires a KV cache hierarchy spanning GPU HBM, host DRAM, and NVMe. The central argument of “KV Cache Tiering and Eviction Policy Design for 128k Context Windows” is that capacity alone does not make this architecture viable. Eviction must account for attention importance, reconstruction cost, and future access, while working with the scheduler to keep transfers from stalling generation.
Why long context makes single-tier GPU memory untenable
KV cache size grows linearly with context length, following O(LHnd) for L layers, H heads, n tokens, and head dimension d. Grouped-Query Attention reduces the constant factor but does not remove that growth. Batch size compounds the pressure across concurrent requests. KVDrive’s May 2026 paper states that a large instruction-tuned model at long context needs a cache exceeding the usable HBM of commodity GPUs, which must also hold weights, activations, and runtime overhead.
Each new token attends over the full cache, so inter-token latency grows as the input gets longer. For these large-model workloads at meaningful batch sizes, GPU HBM alone is too small to hold the cache, so spillover must be part of the system even before tuning.
The bandwidth gap between tiers and what it costs at long context
Moving cache blocks out of HBM exchanges memory pressure for transfer latency. HBM provides TB/s bandwidth, while CPU–GPU PCIe 5.0 provides roughly one to two orders of magnitude less, and NVMe lags further. A large KV payload that takes milliseconds to read from HBM can take hundreds of milliseconds to transfer from DRAM. That delay can come between one generated token and the next. At long context, even one misplaced block can produce a transfer that dominates the decoding step’s latency budget.
KVDrive identifies poor resource overlap as a central failure of naive offloading. GPUs wait for data, CPUs stall during GPU execution, or I/O bandwidth sits unused between transfers. Capacity is available, but execution still stalls. Placement must therefore answer both where a block belongs and when it must move, because a tolerable transfer scheduled too late becomes a foreground delay.
How the canonical three-tier hierarchy is actually structured
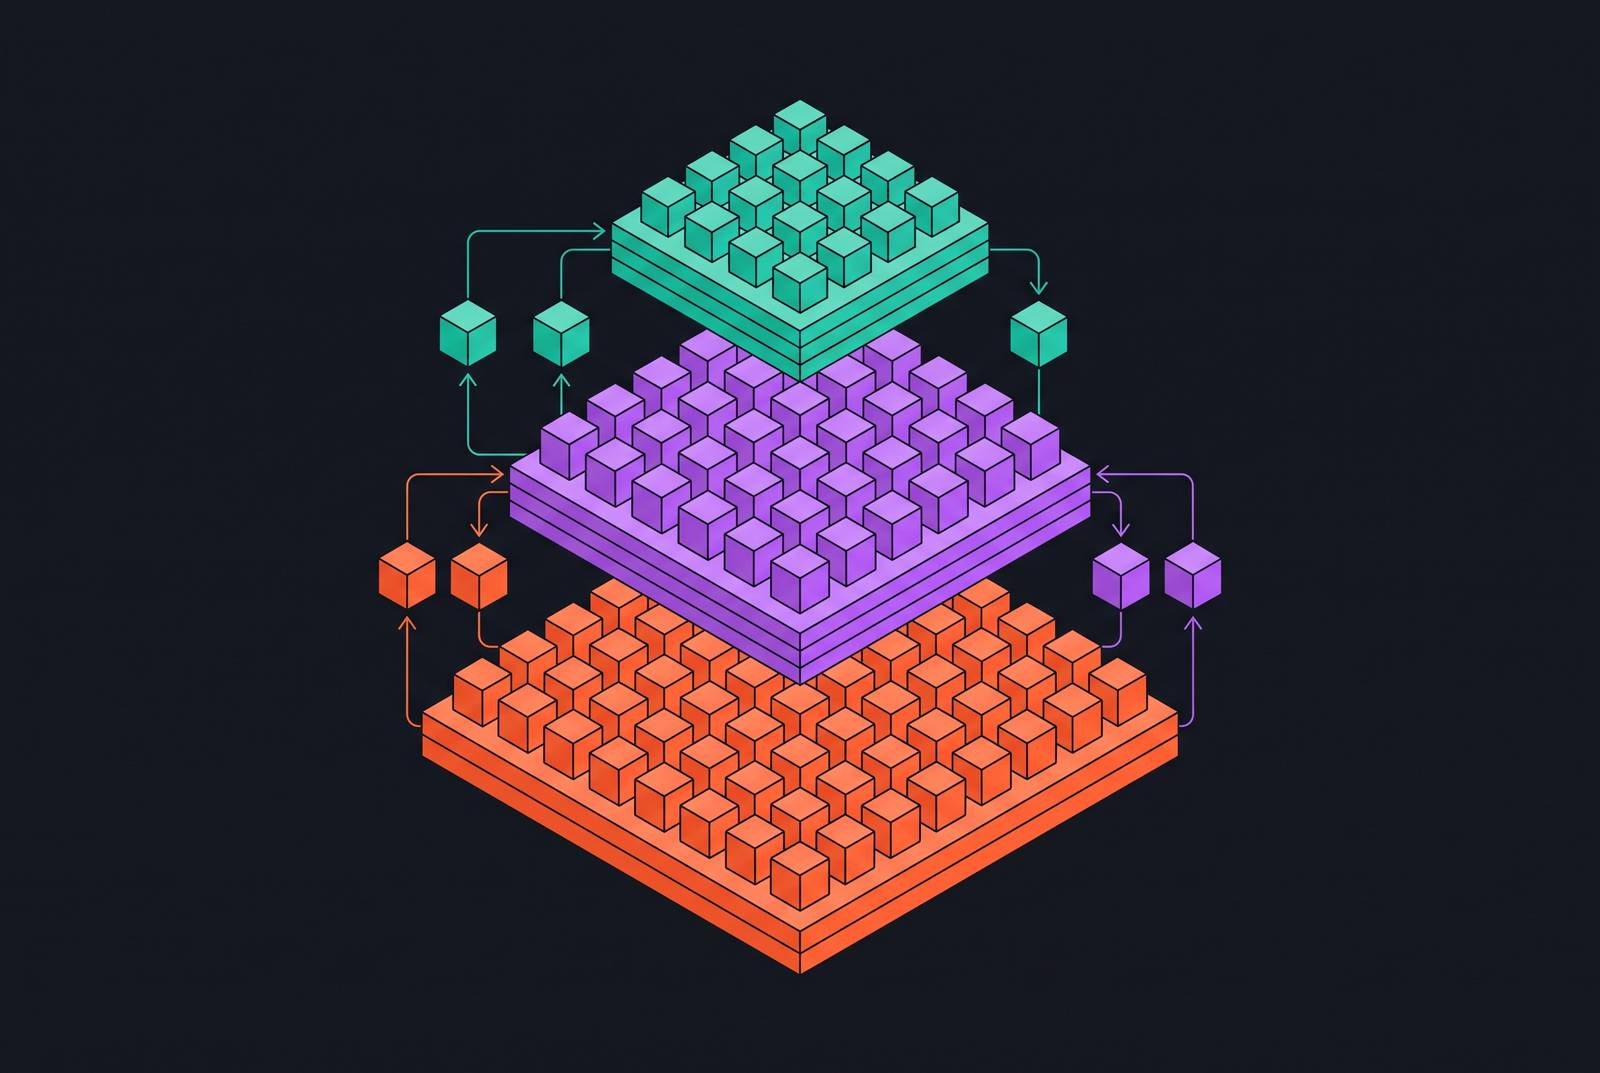
The hot tier holds actively generating blocks and blocks with high attention variance in GPU HBM. Host DRAM forms the warm tier for completed-but-reusable blocks, multi-turn conversation history, and recently prefilled prefixes. These blocks can tolerate reloads when prefetch brings them back before use. NVMe is the cold tier for historical context, prefixes kept for future requests, and blocks that are unlikely to be reused. Each boundary imposes a different penalty for mistaken placement.
LayerKV’s per-layer tracking illustrates why the serving system needs block-level state to avoid coarse-grained thrashing. Evicting from HBM immediately exposes PCIe transfer costs, while fetching from NVMe may cost more than reconstructing the block. That crossover depends on context length, model size, and hardware. It sets a deployment-specific threshold below which retaining a cold block is less useful than dropping it and recomputing it later.
Why standard LRU fails as the eviction policy for this hierarchy
Least recently used eviction ranks blocks by age. That ranking cannot represent the differences between tier boundaries. Two blocks of the same age may have very different recovery costs, because a shallow-layer block with low attention variance is cheap to reconstruct, while a deep-layer block with high dependency and variance costs more. Computation-Aware Tiered Eviction, published in IJPE in 2026, identifies this missing computational expense as a limitation of standard LRU.
A block evicted late in a long conversation may have a high probability of reuse before that conversation ends, without that probability appearing in its age. KVDrive shows that greater sparsity eventually degrades accuracy while transfer volume rises sharply with context length and batch size.
Attention-score eviction: what it gets right and where it breaks down
Attention-score eviction improves on recency by estimating which entries contribute to generation. Importance scores come from historical queries, and an aggregation step usually averages them to rank which entries to keep. This is more selective than a fixed window. StreamingLLM preserves initial tokens and a recent window, but discarding the middle can lose critical information at long context.
DefensiveKV, introduced by USTC in October 2025, shows why mean aggregation remains vulnerable. Individual historical tokens can oscillate substantially in importance across generation steps, undermining the assumption that one subset stays important throughout decoding. The method instead uses a two-step, linear-time defensive aggregation strategy, while Layer-DefensiveKV adds layer-aware allocation and outperforms all baselines on several large open-weight models at aggressive eviction rates.
K-VEC, introduced by RBC Borealis in June 2026, identifies a separate failure in overlapping scores across heads and layers. Retention decisions can repeatedly favor the same tokens, shrinking the diversity of the retained input. Its coverage modules improve results across 16 LongBench subsets, particularly at low cache budgets. The importance measured at prefill may not show which blocks the remaining decoding steps will need.
Lookahead and computation-aware eviction: policies that incorporate future cost
The computation-aware study introduces a controller that scores blocks using attention variance, transformer dependency depth, and temporal locality. Blocks with high scores stay in HBM, while those with lower scores move to an SSD-backed secondary cache. A lightweight runtime profiler updates those scores continuously. Predictive prefetch retrieves blocks before use, and the study reports substantially better sustained throughput than LRU for long sequences without degrading generation quality.
KVDrive evaluates Lookahead eviction across Quest, ShadowKV, RetroInfer, and its own system at a fixed sparsity budget. Hit rates rise in all four systems on both models tested, with gains from small increases to nearly four points. Index memory changes the comparison, however. Quest obtains marginally higher hit rates with an index more than four times larger, while KVDrive achieves comparable hit rates with a substantially smaller footprint.
FlexiCache further distinguishes stable from unstable attention heads, keeping all pages for unstable heads on GPU while offloading most pages for stable heads with periodic reranking. Uniform treatment would waste HBM on some heads and provoke thrashing on others. Scheduling remains inseparable from these retention choices. KVDrive overlaps I/O and CPU/GPU compute stages, demonstrating why eviction and scheduling must be co-designed rather than allowing otherwise sound decisions to generate uneven I/O bursts.
Automated eviction policy discovery and the coverage gap in hand-crafted heuristics
Hand-crafted salience rules can work at moderate eviction rates yet degrade sharply as contexts lengthen and cache budgets tighten. DefensiveKV documents this brittleness across seven task domains and numerous datasets. K-VEC uses an information bottleneck framework to show that reduced token coverage limits mutual information between input and output, then adjusts cross-head attention spans and cross-layer selection to retain tokens not already represented elsewhere.
CacheCraft uses an LLM-guided code-evolution engine to search for scoring rules beyond those written by hand. It searches for a scoring program while keeping prefill single-pass and training-free, without claiming that one fixed heuristic suits every case. The evidence presented concerns policy discovery. Dell Technologies’ KV cache survey concludes that no single optimization dominates across context lengths, hardware constraints, and workloads. That finding points toward adaptive, multi-stage pipelines whose scoring changes through runtime profiling or deployment updates.
KV cache quantization as a tier-compression multiplier at long context
Quantization changes the capacity and transfer arithmetic across the hierarchy. FP8 halves memory per cached token and memory traffic per attention step relative to BF16, reducing the growth of inter-token latency and allowing higher concurrency. NVFP4 reduces cache memory by three-quarters relative to BF16 and by half relative to FP8 on hardware that supports it. Smaller blocks also reduce offload payloads at unchanged PCIe bandwidth.
Accuracy can become the limiting constraint instead. FP8 KV cache with FP8 attention changes average accuracy only slightly on decode-heavy tasks, and MRCR curves for a large Llama model track BF16 closely into long contexts. But vLLM’s analysis reports that full-context needle-in-a-haystack accuracy falls to 13% from a BF16 baseline of 91%. The analysis traces the regression to imprecise FP32 accumulation in Tensor Cores. Two-level accumulation corrections and explicit target-context validation are therefore requirements before deploying this FP8 path.
Hardware mechanisms that change the tier boundary conditions: CXL, RDMA, and GPU-direct NVMe
GPU-direct NVMe through cuFile removes the CPU bounce buffer from the GPU-to-NVMe path, reducing cold-tier access latency. NVIDIA’s ICMSP framework, announced at CES 2026, standardizes this for KV offload with BlueField-4 DPUs handling I/O scheduling. That changes the cold-tier recovery cost used by eviction. Separately, NVIDIA Dynamo’s NIXL, the NVIDIA Inference Xfer Library, supports RDMA-based transfers over InfiniBand without CPU involvement. Its Distributed KV Cache Manager treats combined cluster DRAM and NVMe as a unified KV pool.
CXL-SpecKV, presented at FPGA’26, combines CXL memory disaggregation, FPGA-accelerated compression, and speculative prefetching. It reports over three times throughput and substantially lower memory cost, with accurate prefetch hiding most disaggregation latency. Device semantics are a further condition, however. LM-CXD’s 2026 work connects serving-engine knowledge of upcoming KV consumption with device placement and movement, showing that a stock CXL-SSD without that awareness is no faster than standard NVMe.
NVLink adds another boundary inside a single node. Its GPU-to-GPU bandwidth exceeds PCIe bandwidth, creating an intra-node sharing tier above DRAM when KV state spans GPU devices. Eviction and prefetch timing must use measured latencies from the target stack rather than assumptions inherited from PCIe-attached host memory.
What infrastructure and eviction policy do you need for production long-context serving?
A production team should begin by profiling the actual tier latencies before choosing a scoring policy. PCIe DRAM, GPU-direct NVMe, CXL, and RDMA each establish different transfer costs and prefetch timing requirements. The team should next measure the recompute crossover for its model, context lengths, and hardware. That measurement shows which cold blocks are worth keeping. Systems such as vLLM, SGLang, and Dynamo provide block-table abstractions and multi-tier offload infrastructure, while the underlying storage and interconnects constrain the policies they can support.
Multi-turn conversations with high prefix reuse favor prefix-aware warm-tier management and strong retention of shared prefixes, with recency useful where it correlates with reuse. Long single-document and agent workloads with sparse attention favor top-k importance scoring with defensive aggregation. Heterogeneous high-throughput batches favor computation-aware block scores combined with lookahead prefetch, while multi-document question answering and retrieval-augmented generation need cross-head and cross-layer coverage enforcement.
Quantization should follow accuracy validation at the intended context length, including needle-in-a-haystack testing for FP8 and equivalent scrutiny of NVFP4 and accumulation precision. The scheduler must then overlap I/O and compute around the chosen eviction policy so that transfer bursts do not stall generation. Deployment does not end the calibration process. Instrumenting hit rates, reload latencies, and accuracy allows scoring weights to change at runtime or during updates as the workload shifts.
Sources
- KVDrive: A Holistic Multi-Tier KV Cache Management System for Long-Context LLM Inference
- Taming the Fragility of KV Cache Eviction in LLM Inference
- Coverage-Driven KV Cache Eviction for Efficient and Improved Inference of LLM
- Computation-Aware Tiered Eviction: Optimizing KV Cache Management for Long-Context LLM Inference
- KV CACHE OPTIMIZATION STRATEGIES FOR SCALABLE AND EFFICIENT LLM INFERENCE
- Discovering KV Cache Eviction Policies via LLM-Guided Program Evolution