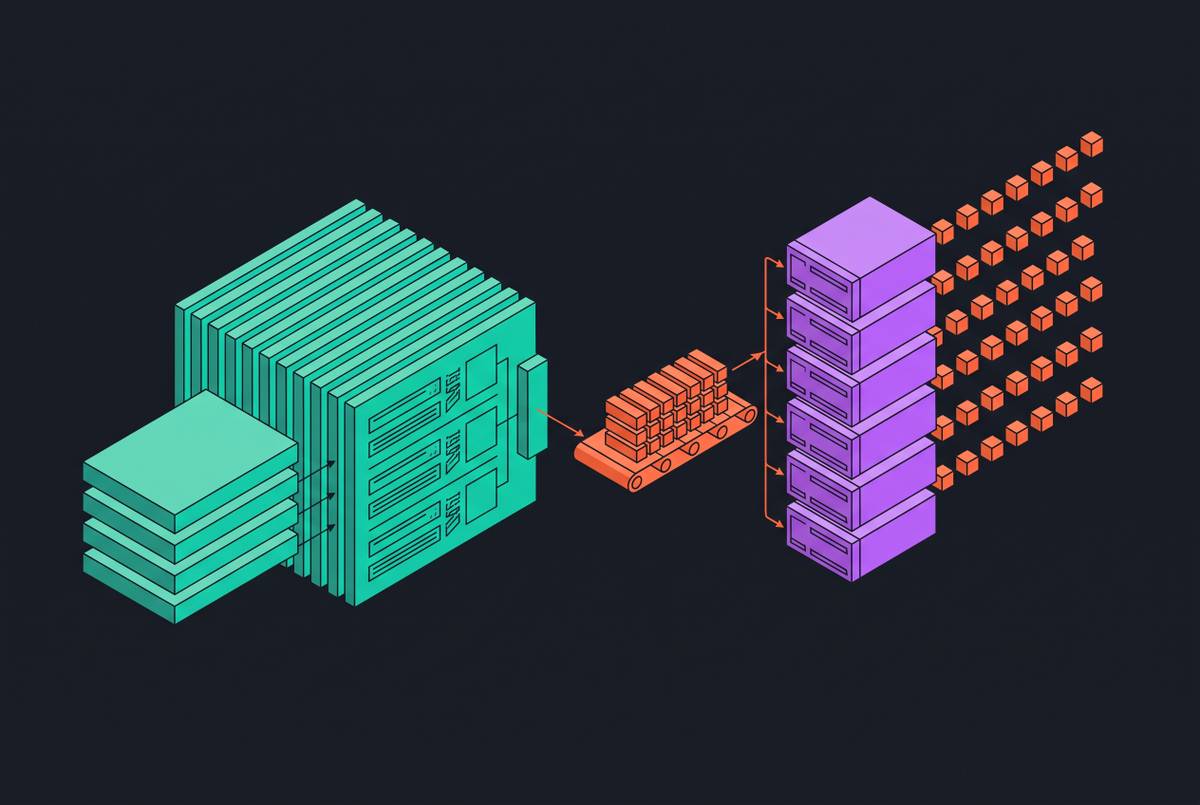
Prefill and Decode Disaggregation in LLM Serving
Splitting prefill and decode workloads cuts latency and improves GPU utilization.
Nikolai Vereshchagin
Section
1 story in Features.
Splitting prefill and decode workloads cuts latency and improves GPU utilization.