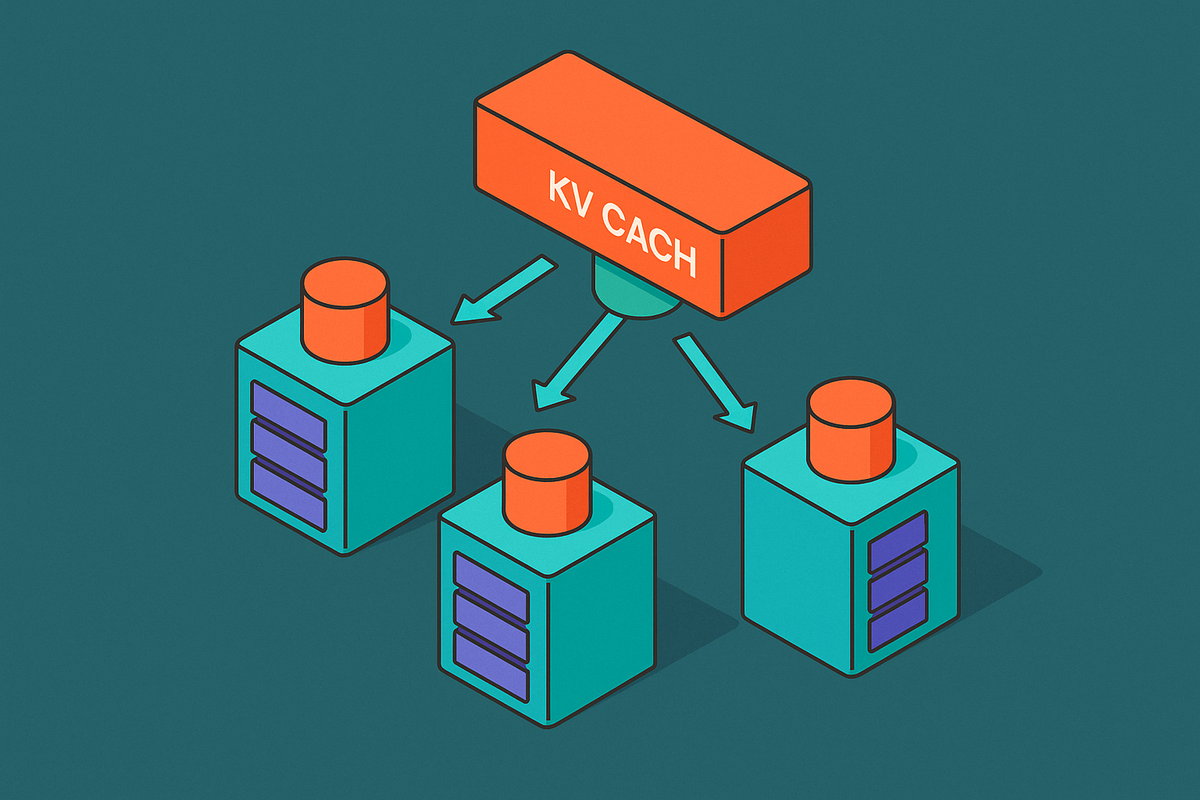
KV Cache Offloading Stack Decisions From GPU DRAM to Object Storage
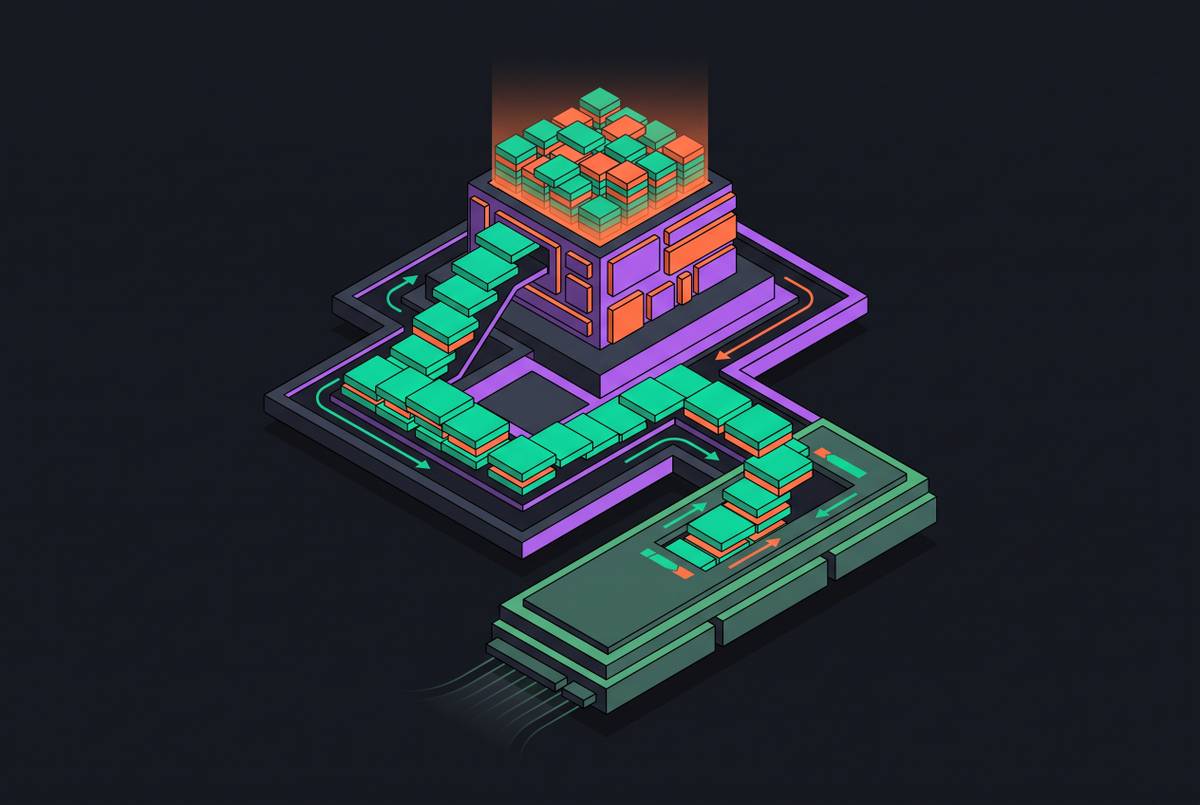
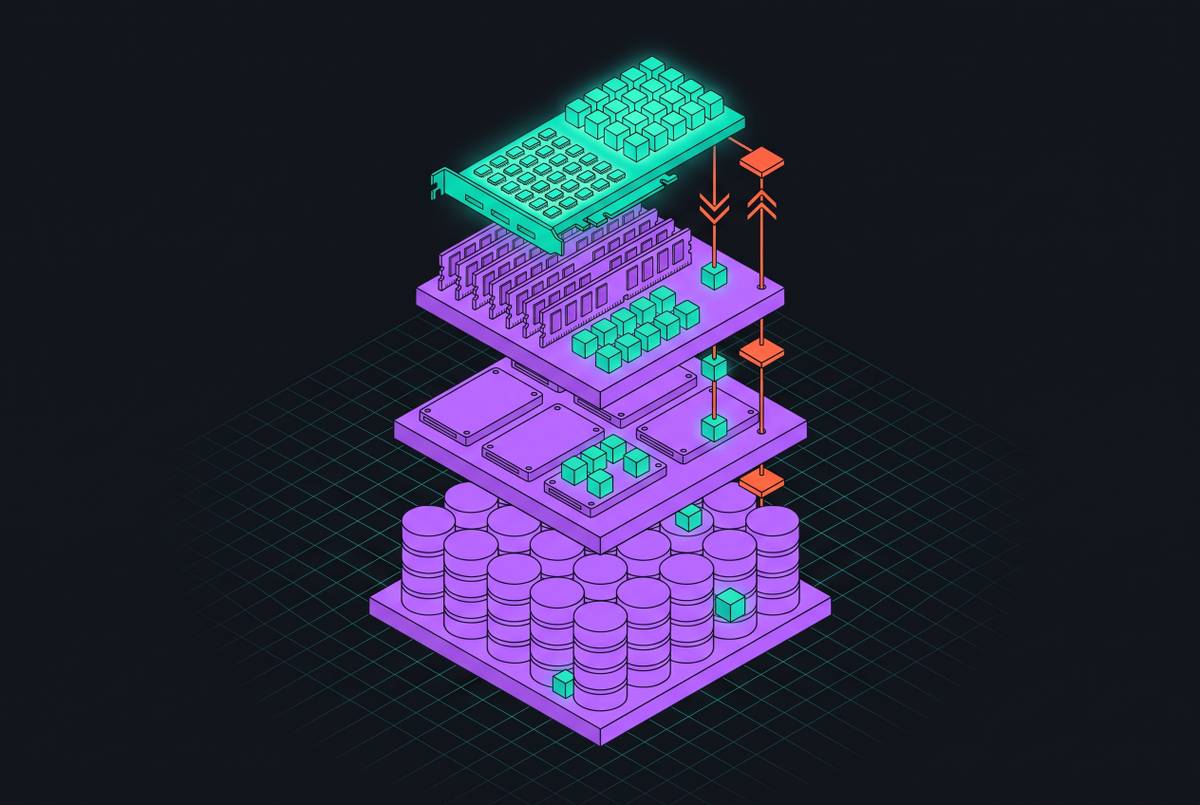
How to move LLM cache between GPU, DRAM, and storage.
Amara Osei-Bonsu
Section
10 stories in KV Cache Systems.
How to move LLM cache between GPU, DRAM, and storage.
A four-layer framework combines paging, quantization, eviction.
Managing KV cache as a shared resource across request lifecycles improves LLM serving efficiency.
How to predict GPU memory limits before your inference server crashes from hidden cache overhead.
Splitting inference across nodes requires moving KV cache efficiently between machines.
Offloading KV cache to NVMe requires bypassing the CPU bottleneck entirely.
How vLLM reuses cached token blocks to slash GPU compute waste across requests.
How a virtual memory trick cuts KV cache waste from 80% to 4%.
Memory layout decisions determine whether multi-GPU serving saturates compute or bandwidth.
LRU fails on long contexts, but GDSF and attention-aware policies offer concrete improvements.