LRU vs GDSF vs Recency-Weighted Eviction for Long-Context KV Cache
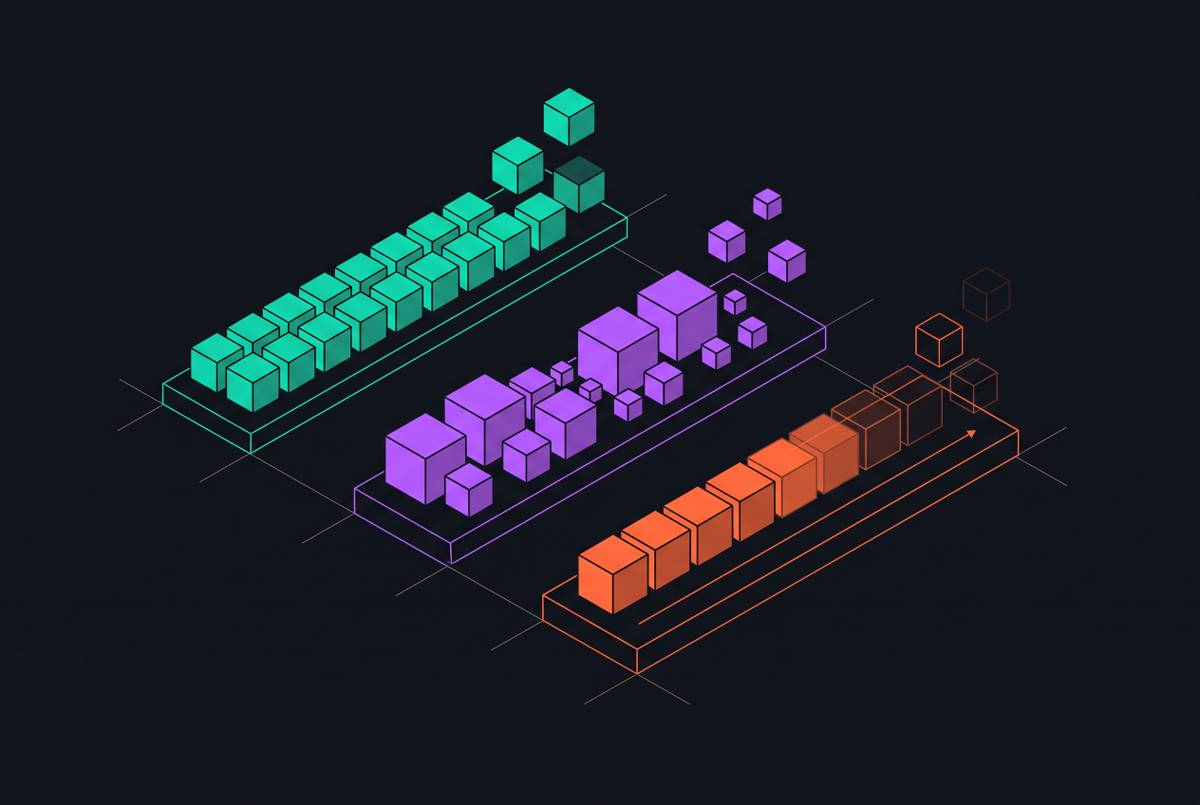
LRU fails on long contexts, but GDSF and attention-aware policies offer concrete improvements.
Amara Osei-Bonsu
Memory layout decisions determine whether multi-GPU serving saturates compute or bandwidth.
LRU fails on long contexts, but GDSF and attention-aware policies offer concrete improvements.
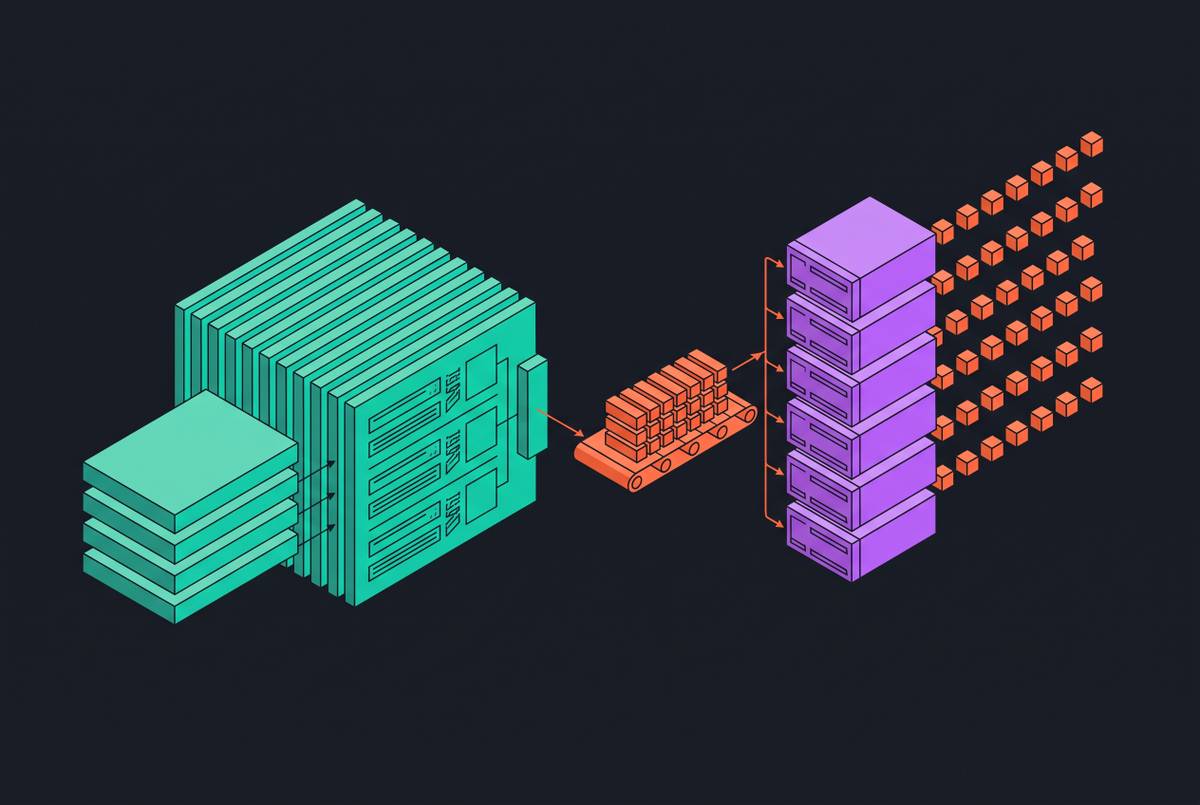
Splitting prefill and decode workloads cuts latency and improves GPU utilization.