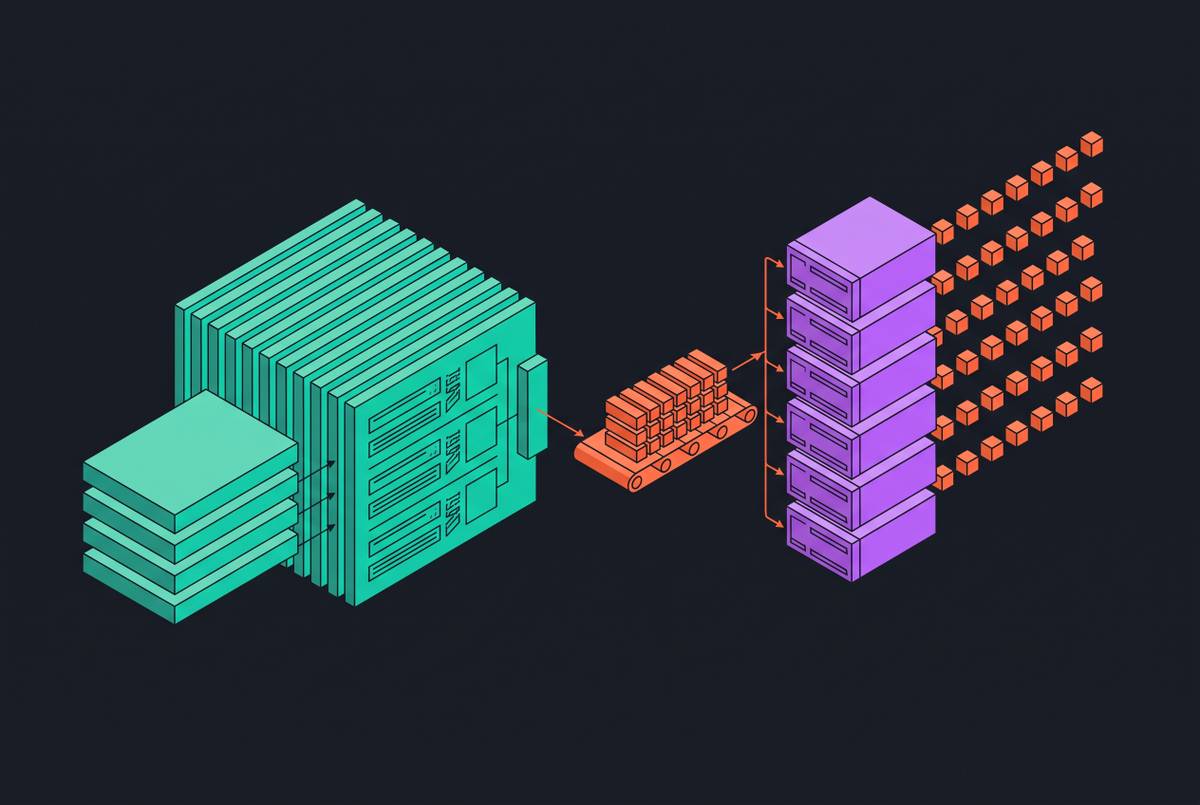
Prefill and Decode Disaggregation in LLM Serving
Splitting prefill and decode onto separate GPUs unlocks independent scaling for LLM serving.
Nikolai Vereshchagin
Staff Writer
Nikolai Vereshchagin spent six years as a compression algorithm researcher at a European telecommunications equipment company before shifting to technology journalism, where he now covers the intersection of data encoding, lossless pipelines, and the storage economics of large-scale AI deployment. His work frequently bridges theory and production realities.
1 story
Splitting prefill and decode onto separate GPUs unlocks independent scaling for LLM serving.