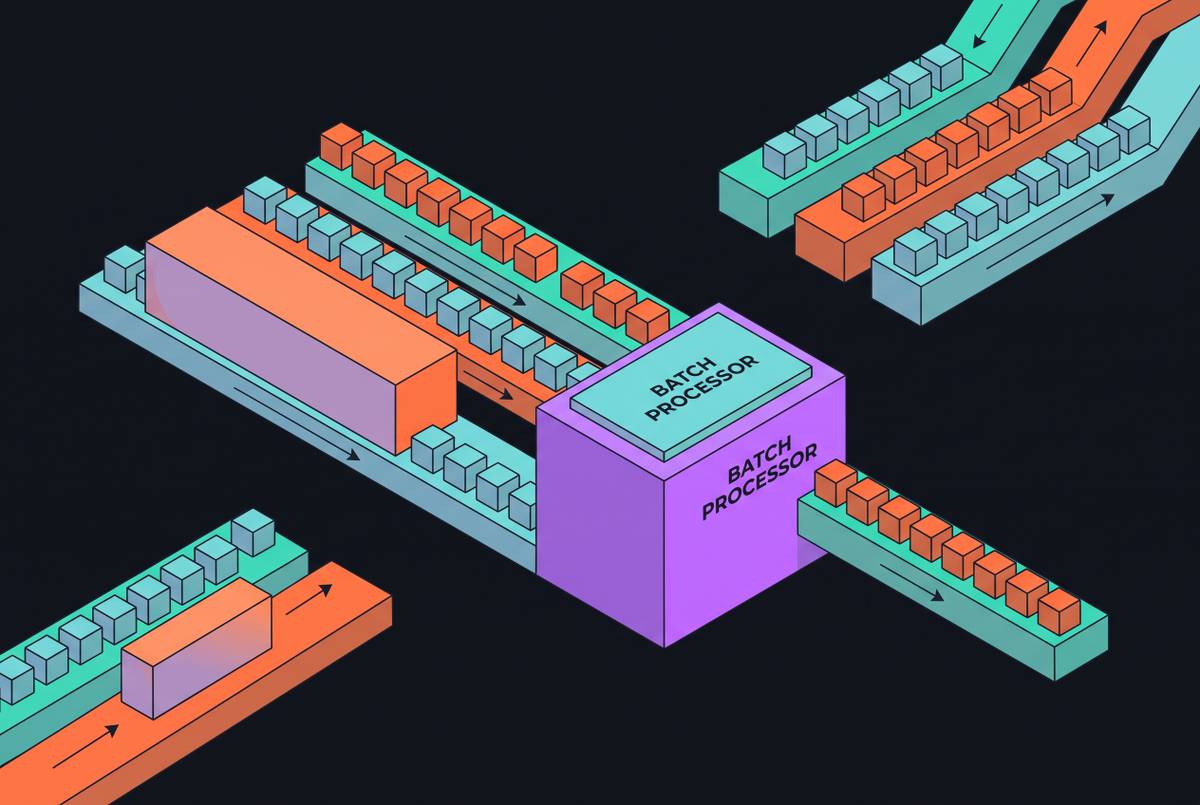
Continuous Batching Mechanics and Head-of-Line Blocking
Continuous batching solves one head-of-line problem but leaves two deeper mechanisms intact.
Priya Subramaniam
Senior Staff Writer
Priya Subramaniam has spent over a decade covering systems software and hardware co-design, previously embedded with semiconductor research teams in Austin and Bengaluru before focusing exclusively on AI infrastructure. Her reporting zeroes in on how memory hierarchies and storage pipelines shape real-world inference latency at scale.
5 stories
Continuous batching solves one head-of-line problem but leaves two deeper mechanisms intact.
Splitting inference across nodes requires moving KV cache efficiently between machines.
Offloading KV cache to NVMe requires bypassing the CPU bottleneck entirely.
How vLLM reuses cached token blocks to slash redundant GPU computation.
Attention architecture determines KV cache size; wrong block sizing wastes bandwidth on every token.